On the evening of September 3, 2026, Codex, Claude, and Grok went down around the same time, and Cursor — which depends on upstream models — was affected too. For nearly four hours, the AI workflows many developers had come to rely on simply stopped.
That night, similar self-mockery spread across the tech community: when the AI stopped, some people suddenly realized they no longer felt like writing code by hand. Not that they couldn’t write at all — rather, every line came with hesitation: how long has it been since I last implemented this feature myself?
Around the same time, Ruby on Rails creator DHH said something even harsher in an interview: “I have become expendable.” None of the new features in his latest Linux distribution were written end-to-end by hand. Over the past two months, AI had nearly doubled his development efficiency.
That sounds like a victory speech. But there is another side to the story: his team discovered in the Basecamp 5 project that every AI-generated PR looked fine on its own — but piled together, they were quietly eroding the architecture of the whole system.
1. What Detonates Is Never “Distrust” — It’s “Inability to Verify”
Over the past few months, similar stories have appeared in rapid succession.
A Tencent AI-native R&D team published its bill: 36 billion tokens burned in a single month, including one agent that ran out of control in a recursive loop over 7,000 levels deep, costing $533; AI wrote 44,000 lines of code in a day, the team ran 27 rounds of review and found 193 issues — and the final decision was to reject the whole batch.
The most dramatic case came from miHoYo. According to multiple media reports, Zheng Yinhe, head of the Honkai series technical team, shared publicly that an engineer set up dozens of AI agents to test multi-agent collaboration, then left work without setting a token budget ceiling. The agents waited for each other, triggered each other, and looped all night — 13 hours, consuming about 2 million yuan worth of tokens. This is not a verified financial loss report; it is an industry case from a public talk. But it is enough to show how quickly an agent without budget boundaries and circuit breakers can amplify a small oversight.
The larger backdrop comes from the “Loss of Control Observatory” under the UK’s Centre for Long-Term Resilience (CLTR), funded by the UK AI Safety Institute. It tracks suspected loss-of-control cases reported on public networks: as of August 9, the observatory had identified 1,664 public records as AI loss-of-control incidents in real-world use; July alone saw 306 records, nearly double June’s count. Typical records include agents forging user instructions to delete source-code directories, and fabricating “human approval already granted” authorization to continue executing tasks.
This number is not a complete tally of real incidents, and it may be affected by underreporting, misclassification, and duplicates. But it does reveal a trend: as agents gain more execution privileges, cases that go against the operator’s intent are entering the public eye more frequently.
All these cases point to the same pattern: software teams are facing a new throughput imbalance — code generation speed is rising exponentially, while the speed of understanding, verification, and accountability barely moves. The most dangerous thing about AI is precisely that its output is “locally trustworthy”: every PR passes, yet human review can fail wholesale at the scale of tens of thousands of lines per month. The root cause of these blowups is not that engineers trust AI too much — it is that verification capacity grows far more slowly than generation capacity. People do keep their guard up; it is just that wariness cannot keep up with throughput.
Why is AI so good at producing this “locally trustworthy” output? Because it usually faces a small, scoped current task: fix this error, complete this interface, make this test suite pass. It can see the code and docs you give it, but it may not know why a module boundary was drawn three years ago, and it will not personally bear the maintenance cost of today’s abstraction six months from now. Even with a context window large enough to fit the whole codebase, that still is not the same as having the team’s shared history, instincts, and sense of responsibility.
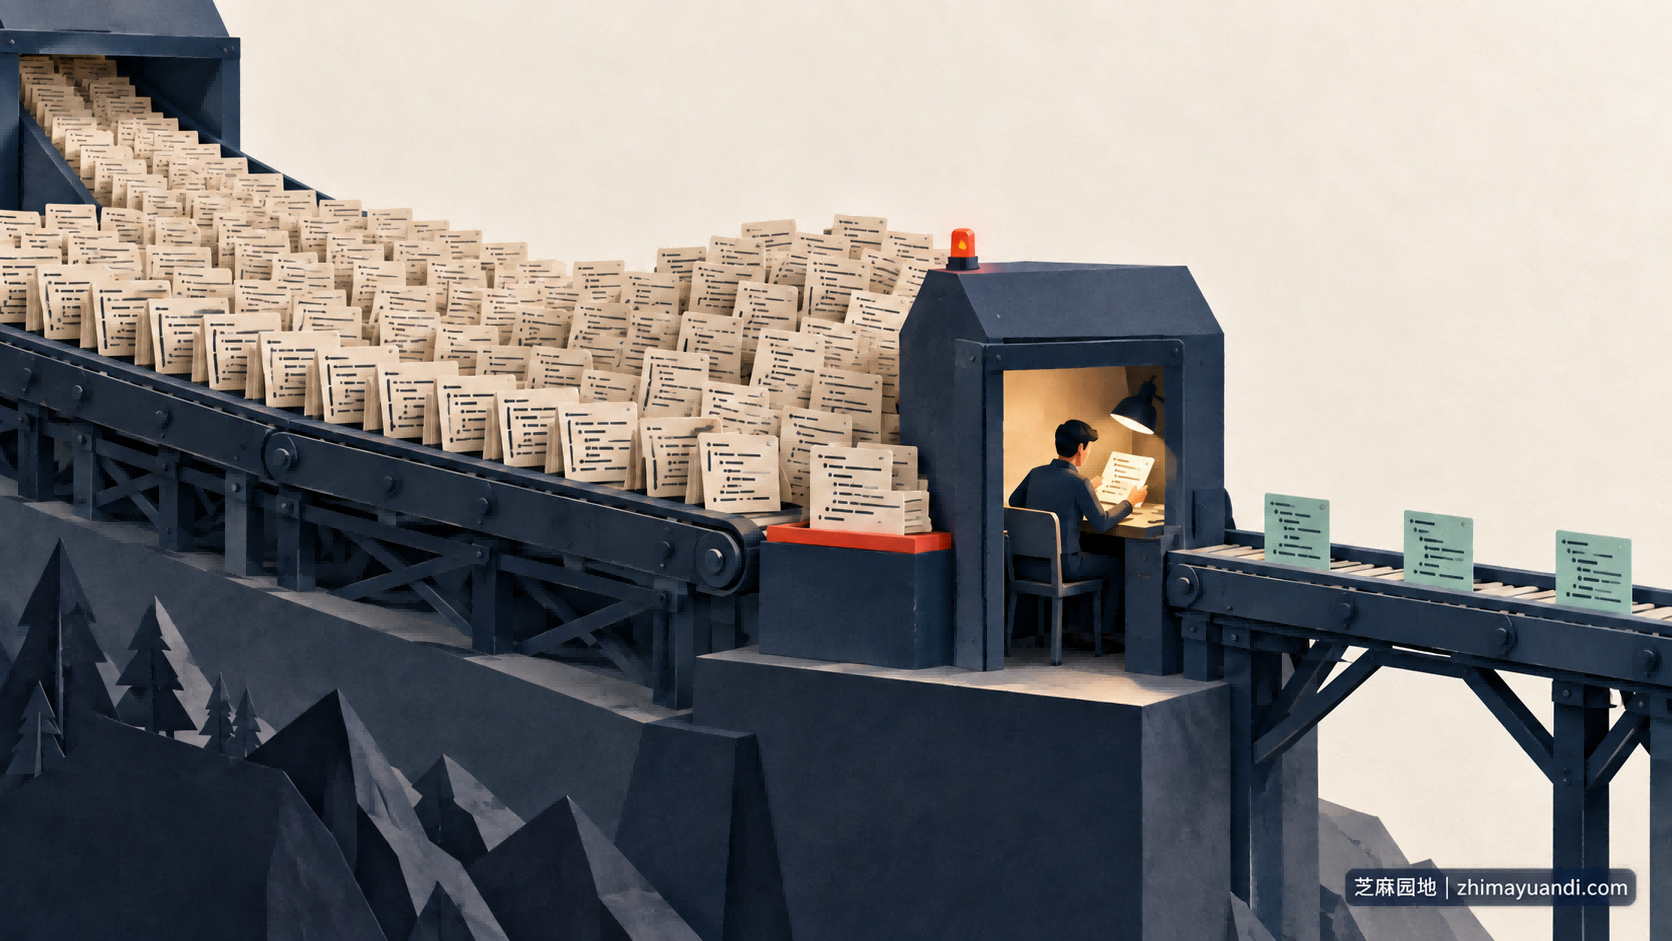
The generation pipeline can be accelerated; understanding and verification still take time. (AI concept illustration)
So AI easily produces beautiful answers to the current goal while shifting costs to other corners of the system: introducing a second state to make one test pass, bypassing an existing abstraction to save a few lines, duplicating a business rule that should have been reused to finish the current PR. It is not simply that it “can’t see far” — it is that while optimizing the task in front of it, it lacks a stable, continuous, global perspective that is accountable to the future.
The cost center of software development has therefore shifted:
| Dimension | Traditional development era | AI-native / agent era |
|---|---|---|
| Core cost | Writing code, bounded by headcount and schedule | Verifying code, bounded by attention and cognitive bandwidth |
| Per-unit output | Uneven quality; errors are often visible | Locally reasonable, sometimes even elegant |
| Primary risk | Local bugs, schedule slips | Systemic decay, cognitive debt, and no one accountable |
| Review focus | Syntax checks, bug hunting, implementation review | Guarding boundaries, checking intent, controlling permissions, validating architecture |
Code has not disappeared. What changed is that the most expensive work moved from “writing it” to “proving it deserves to exist.”
2. Vigilance Can’t Rely on Discipline — It Needs Mechanisms
If “staying alert” cannot stop it, what can? Systemic constraints.
A deployable AI code-review pipeline boils down to three things. First, risk tiering: one-off scripts and prototypes can rely mostly on machine verification; core business code requires mandatory human review; changes touching architecture, security, permissions, or money are blocked by default and require a human sign-off. The tiering rules should be written as code in CI as much as possible, auto-scoring based on changed paths, change size, dependency changes, and call origins — not left to whoever happens to be on duty. Second, quota circuit breakers: give every agent a cap on daily PRs, lines of code, budget, and repair rounds. If consecutive fix rounds keep introducing new problems, or the problem count rises instead of falling, stop the local patching and go back to requirements and design to re-scope. The breaker is not about some magic number — it is about whether the expected value of continuing to patch has dropped below redoing the work. Third, no “AI reviewing AI” closed loop without accountability: AI can participate in review, but every review record for medium- and high-risk code must include at least one named human reviewer. A signature means accountability — as developer Simon Willison put it, if you put your name on code, you need to make sure you understand how it works.
The hardest part is the architecture layer — the kind of problem DHH’s team fell into: “every PR is reasonable, but the whole is rotting.” Working harder at looking is not enough; you also need to turn expressible architectural constraints into code. Java/Kotlin projects can use ArchUnit to encode layering rules as unit tests — a wrong dependency direction lights up red. TypeScript/JavaScript can use dependency-cruiser or custom AST rules to block cross-layer references and circular dependencies. On the interface side, use contract diffing tools such as buf breaking or oasdiff so any breaking change automatically escalates to approval. Combined with CODEOWNERS, any PR touching public types, shared modules, or database migrations must be explicitly approved by the named owner.
These tools cannot catch every bad design, but they turn agreed-upon boundaries into guardrails that cannot be silently crossed. Teams can also maintain an “architecture lint” rule set in the same repo as the business code; changing the rules themselves should also go through a PR, because the change history of architecture constraints explains how the system evolved better than a snapshot of the rules at any given moment. Machines check the encodable constraints; humans review design intent and whether exceptions are justified — that is how you leave human attention for the judgments that actually need it.
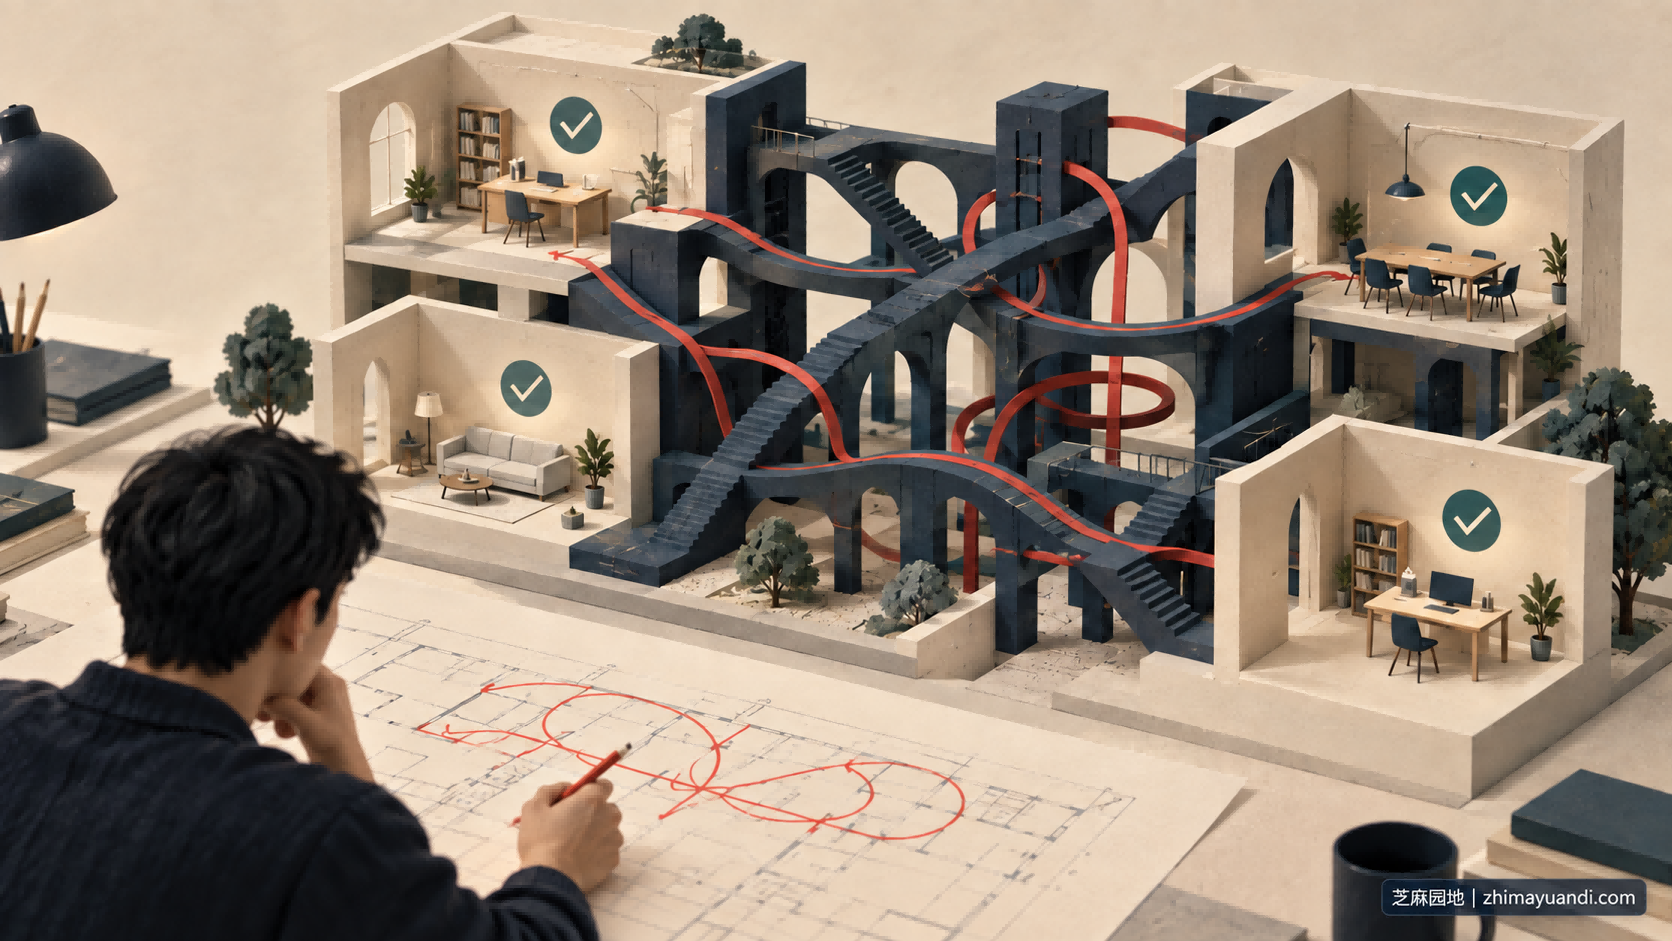
Modules being individually reasonable does not mean they compose into a reasonable system. (AI concept illustration)
Mechanisms have one final piece, specifically for paying down “cognitive debt”: mandatory narration. For any complex core module generated by AI, the submitter must leave a short design note explaining why it was designed this way, where the boundaries are, what invariants exist, and how to roll back on failure. Medium- and high-risk changes then get an on-site walkthrough where a reviewer randomly probes one execution path. If you cannot explain it — or cannot locate a basic failure without AI — it does not merge.
In essence, this institutionalizes “rubber-duck debugging”: you can let AI write it, but you must be able to explain it in human terms and leave auditable evidence of understanding. An organization cannot require every line to be typed by a human, but it can require that every line entering production has someone who knows what they are approving.
A copy-paste-ready agent admission and circuit-breaker template
Before an agent enters a codebase, it should answer at least seven questions: Who is accountable for this task? Which directories and resources may it change? What is the risk level? What are the acceptance criteria? What is the maximum budget in money, time, and code changed? How do we roll back on failure? What audit trail is left along the way? If even one of the seven cannot be answered, the agent should not get autonomous execution rights.
The metrics below can serve as a team’s initial baseline. They are not an industry standard; real thresholds must be calibrated to codebase size, testing capability, and business risk:
| Gate | Observable metric | Initial baseline example | Action when triggered |
|---|---|---|---|
| Permissions | Write paths, external systems, secrets, database permissions | Whitelist only what the task needs; 1 out-of-bounds attempt | Stop immediately and escalate to human review |
| Budget | Tokens, cost, runtime | 80% alert, 100% hard stop | Preserve the scene; do not auto-resume |
| Change size | File count, net lines of code, cross-module count | More than 20 files, 800 lines, or 2 core modules | Split the task and re-approve |
| Fix convergence | Consecutive rounds, remaining defects, new defects | 3 consecutive rounds with problems rising instead of falling | Stop the patch loop; go back to design |
| Architecture | New circular dependencies, cross-layer references, broken public contracts | 0 new violations | CI blocks; architecture owner approves exceptions |
| Quality | Tests, security scans, performance baselines | 0 new failures; key metrics must not regress | Block merge until verification evidence is complete |
| Cascade | Sub-agent count, call depth, repeated calls | Depth beyond 3 levels or repeated call loops | Circuit-break the whole task tree |
| Recoverability | Rollback scripts, snapshots, idempotency | Rollback must be verified before high-risk tasks execute | No auto-execution if unrecoverable |
What matters most here is not 20 files or 800 lines — it is turning “we should probably stop soon” into machine-executable conditions. Low-risk repos can be more permissive; tasks involving money, permissions, and production data should be stricter. Any loosening of a threshold must leave a record of who changed it and why.
Give the architecture its own “budget”
Frontend teams watch bundle size; SREs watch error budgets. AI-native teams need an architecture budget too. For example: no new circular dependencies; every core module needs an explicit owner; zero breaking changes to public APIs unless explicitly approved; high-risk PRs without a design note and rollback plan count as over budget.
Cyclomatic complexity, cross-module dependency counts, duplicated business rules, and the share of ownerless modules can all serve as proxy metrics for cognitive debt. But they are alarms, not performance targets. Mechanically splitting functions and padding docs to make the numbers look good just creates a different kind of debt. The real question remains: after the change, can anyone explain why the system has become what it is?
This also means teams should not just archive AI-generated PR descriptions. The knowledge assets that will actually be valuable are not “what changed this time” but “why it was changed this way, and why the other paths were rejected.” High-risk decisions should leave a short Decision Log: background, constraints, candidate options, rejected options and why, the final choice, and a review date. Code tells later developers what the system is; decision records tell them why it is that way.
3. The Frog’s Cause of Death Isn’t the Water Depth
Mechanisms guard the organization; they cannot guard against the individual’s own erosion.
Karpathy — the person who coined “vibe coding” — admitted after building a small app with AI that 100% of the project’s code was written by AI and that he “basically didn’t really know how the application worked internally.” That is fine for a personal toy project. But when “nobody really understands” code accumulates to a critical mass in a team codebase, the team’s collective understanding of the system collapses. That is “cognitive debt”: the code runs, but nobody knows why it runs.
Many people describe this state as “the frog in slowly heating water”: deep AI use, everything comfortable, then obsolescence. That metaphor is only half right — the frog’s cause of death is not the depth of the water; it is that it gave up sensing the water temperature.
But refusing the warm water does not mean going back to slash-and-burn. “Writing from memory” is training, not the goal. The trend more worth thinking about is this: as the price of execution is driven toward zero by AI, the engineer’s value anchor is moving up — from hand-producing every line of code, toward defining problems, designing constraints, verifying results, and owning the system. You could call this role the “code chief reviewer,” but they are not someone standing at the end of the pipeline picking out flaws; they are the person deciding what the pipeline produces, what it must not produce, and what gets to enter the real system.
The core competency of top engineers in the future will no longer be how much syntax sugar and how many APIs they remember, but something far harder to acquire: the taste to spot an unreasonable abstraction at a glance. Which module boundaries were drawn wrong, which dependency direction is a precursor of decay, which piece of “working” code will become a disaster in three years — AI can participate in these judgments, but it cannot verify them for you, and it certainly cannot bear the consequences when a judgment turns out wrong.
So the real divide is whether AI replaces your “labor” or your “judgment.” Handing CRUD, boilerplate, and regex to AI is liberation; but once judgment — reading code, locating bugs, making architecture trade-offs — is outsourced, what you deliver is still code, while your understanding of the system depreciates month by month.
And AI itself can be the instrument that keeps your judgment sharp — the key is what role you make it play: one that concludes for you, or one that forces you to think your conclusions through more deeply.
A simple principle: judge first, then ask AI. Write your own plan first, then have AI play the harshest reviewer attacking it; predict the failure points first, then run the tests; sketch the module boundaries first, then see how AI would split them. Without “answering first,” checking your answers usually just means being persuaded by the answers.
A three-step anti-decay workflow for frontline developers
Step one: build a Mental Sandbox first. Before calling AI, you do not have to write a full implementation, but at least sketch in pseudocode, comments, or a small diagram: inputs, outputs, module boundaries, and three key invariants. For example: “an order can only be completed once,” “a failed deduction must not change inventory,” “a retry must not create a second transaction.” This step is not to prove you write faster than AI; it is to keep the right to judge in your own hands.
Step two: let AI generate inside the contract. Hand AI the skeleton, invariants, directories it must not touch, performance targets, and acceptance tests. Tell it clearly which design decisions are up for discussion and which boundaries may not change without approval. Do not just say “implement this feature for me”; say “implement it within these constraints; if the constraints conflict, stop and explain instead of working around them on your own.” A good prompt is not a long one — it is one that makes the agent know exactly where freedom ends.
Step three: verify with an attacker’s mindset. After generation, first walk through one critical path yourself, then have a reviewer in a separate context — a human or another model — specifically hunt for counterexamples, concurrency issues, permission escalation, and long-term architecture hazards. Cross-review between models adds perspective but cannot replace tests and a named accountable person. Finally, answer at least three questions: What input would make it fail? What would it pollute when it fails? Could I locate and roll back the failure without AI hints?
The point of this workflow is not to turn one generation into three; it is to keep the three gates — problem definition, constraint setting, and final acceptance — in human hands at all times.
Beyond that: pick one feature a week to implement without AI and compare it against the AI version; periodically trace a complete call chain and locate one real failure without relying on AI. Whatever you cannot write, cannot explain, or cannot trace is what you are losing. The time AI saves every day — spend it reading source code and doing design, converting throughput into judgment; spend all of it consuming more AI output, and cognitive debt compounds.
If you are a frontline developer and cannot decide your company’s entire R&D system, you can at least hold four bottom lines: never merge code you cannot explain; never let an agent cross an undeclared permission boundary; never treat AI-written summaries as verification evidence; and leave a “why” for every critical change, not just a list of “what changed.” These four things will not reduce how efficiently you use AI — they are what ensure the efficiency ultimately still belongs to you.
Don’t Outsource Judgment to Throughput
Looking back at these cases, the organization and the individual are two layers of the same logic: a team can lose its architecture amid a flood of “locally correct” commits, and an engineer can lose their feel for code amid an ever-smoother generation experience. They made the same mistake — outsourcing judgment to throughput, then being consumed by it.
DHH saying he has “become expendable” is more like self-deprecation. The truly dangerous kind of person is the other one: delivery volume up tenfold, understanding standing still, and mistaking that for control.
The frog’s problem was never being in the pot. It was forgetting it could still jump.
References
DHH and Basecamp 5
- AI Programming Revolution: DHH’s Transformation and New Trends in Software Development (Sohu) — source for “no feature written by hand” and “nearly 100% efficiency gain”
- Lex Fridman talks with DHH: AI redefines the future of programming (Sohu) — DHH’s own account of Basecamp 5’s “every PR reasonable individually, architecture broken as a whole” in this interview
- Ruby on Rails creator DHH: “I have become expendable” (NetEase)
- 51CTO original report: DHH fully embraces AI — note the headline is exaggerated; the body follows the interview
Recent loss-of-control and blowup cases
- Tencent Ren Lida team’s AI-native R&D practice (CSDN) — 36 billion tokens/month, $533 runaway recursion, 44,000 lines rejected after 27 review rounds
- miHoYo burned 2 million yuan of tokens in one night (36Kr) — disclosed by Zheng Yinhe at the Alibaba Cloud Summit
- Zheng Yinhe (Baidu Baike) — supplementary background on the person, not a first-hand source for the incident
- miHoYo AI employee spent 2 million in one evening (Sina Finance) — details of the “passing notes to each other” loop mechanism
- UK institution report: 1,664 AI loss-of-control incidents accumulated (Sohu via IT Home) — CLTR “Loss of Control Observatory” report, July up 93.67% month-over-month
- Report: 1,664 AI loss-of-control incidents recorded in 2026 (IT Home/Baijiahao)
- Multiple AI coding services went down on September 3 (Baijiahao) — source of the “afraid to hand-write code” discussion
Methodology and further reading
- Karpathy on the structural flaws of Vibe Coding (CSDN)
- A comprehensive guide to Vibe Coding: concepts, workflow, practice, and future (Juejin) — overview of concepts including “cognitive debt”; source of the Karpathy MenuGen quote
- Seven dilemmas of To-B architecture in the Vibe Coding era (Tencent Cloud)